Mathematics over Coffee: A Glimpse of Erdős's Probabilistic Method
Must a mathematical proof reach its answer step by step? The mathematician Erdős offered a wonderfully indirect idea: if we can prove that “a random choice has some chance of success,” then we have proved that a solution exists. Pour yourself a coffee and enjoy these proofs as works of art.
Author: silverxz
Reviewed by: phy东西
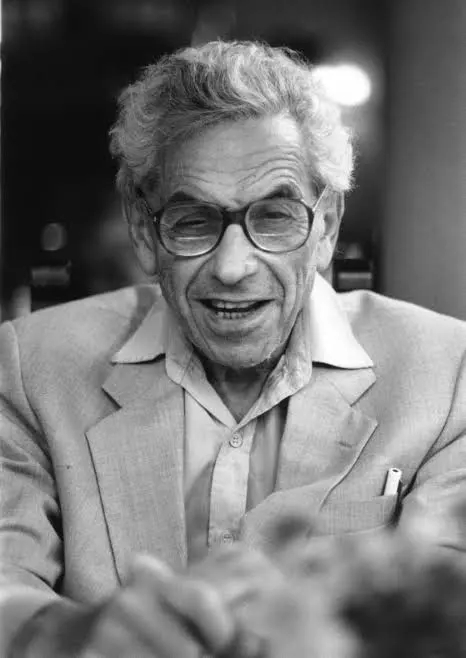
Paul Erdős may not be a household name, but nearly everyone in mathematics knows who he was. A prolific and wide-ranging mathematician, he produced remarkable results in number theory, set theory, analysis, geometry, and many other fields. His place in combinatorics is beyond dispute.
There is no shortage of stories about Erdős: his unusual way of living and doing mathematics, the many forms his brilliance took, and much more. You can read those stories elsewhere; they are not our subject today. Instead, we will look at a fascinating technique that Erdős helped popularize: the probabilistic method.
You may be wondering whether this is simply a technique from probability theory. Why give it such a broad and vague name?
Not quite. The probabilistic method is not a method within probability theory. The idea is to start with a deterministic problem unrelated to probability, deliberately build a probabilistic structure around it, analyze that structure with probabilistic tools, and then use the resulting probabilistic statement to recover the deterministic conclusion we wanted in the first place. Put another way, the method “introduces probabilistic structure into a non-probabilistic problem in order to solve it.” Probability is only the scaffolding, much like an auxiliary line in plane geometry.
That is exactly what makes the method so striking. How can probability enter a problem that has nothing to do with it? And can it really help?
We will work through several short, entertaining examples and watch the method in action. Erdős’s probabilistic method is usually associated with combinatorics, but its uses extend far beyond that field, so I have chosen examples from several areas. Each one is light enough to serve as dessert and should not be too taxing. The article is long only because the explanations are detailed; it should go by much faster than a typical mathematics article of the same length.
Some elementary linear algebra and probability will help. Beyond that, the stronger your mathematical background, the more “relaxed and leisurely” the reading will feel. Ideally, you can make a cup of coffee on one or two quiet afternoons and wander pleasantly through the examples. I hope they remind you how beautiful mathematics can be.
Vector Balancing: The Basic Framework of the Probabilistic Method
Let us begin with a particularly simple example of what it means to “introduce probabilistic structure into a non-probabilistic problem.”
Let there be vectors , and let denote the length of vector . Prove that there are signs such that
The task is to balance the vectors by adjusting the coefficients , keeping the resulting vector as short as possible. The geometry becomes clear after a moment’s thought. Imagine two vectors in . Their sum is relatively short when the angle between them is obtuse and longer when the angle is acute. We therefore choose the coefficients so that each new vector makes a nonacute angle with the sum of the vectors before it.
The sign of the dot product tells us about the angle between two vectors. Write the dot product of as , and let the sum of the first vectors be
Of the two choices , take the one for which . This is the coefficient-adjustment step. Then
The original statement now follows by induction.
But you are probably wondering: where was the probabilistic method? Can a proposition this simple, with such a clear interpretation and such a short proof, really have another proof? Let us find out.
Treat the as independent uniform random variables on . The square of a vector’s length is its dot product with itself, so
The last equality uses the independence of the . When , ; when , .
Under a random assignment of the , the average value of is There must therefore be at least one fixed assignment for which is no greater than : not every value can lie above the average. That completes the proof. It does not construct the particular values of the , but it does prove that the values we need exist.
The two proofs are almost “equally simple,” yet they proceed in entirely different ways. The second shows the basic framework of the probabilistic method. First, randomize the deterministic problem by treating the as random variables. Second, analyze the new construction with probabilistic tools. Here we take an expectation and use independence to dispose of every cross term with in one stroke. Finally, convert the probabilistic statement back into a deterministic one. An almost trivial observation such as “not every value can exceed the average” guarantees that the desired value exists. That existence statement is completely deterministic and no longer depends on the probabilistic structure used to reach it.
But… but… who would ever think to solve the problem this way? The question is no longer just “Why does this work?” but “How did anyone come up with it?” Good mathematics teaching should normally do more than present a proof. It should unpack the motivation and technique so students can master the idea and apply it elsewhere. But as the title and introduction suggest, this is coffee-break reading, not a lesson burdened with too many educational duties. I would rather you read it as a mathematical joke book. We will enjoy the examples and their proofs without digging deeply into their motivations, extensions, and so forth.
Random Translation and Covering with Unit Disks
Our second example is a problem posed and solved in 2008 by the Japanese “puzzle designer” Naoki Inaba:
Prove that any given set of 10 points in the plane can be covered by a collection of pairwise disjoint unit disks, meaning disks of radius .
Throughout this section, “disjoint” means that the interiors of the disks do not overlap. The disks may be tangent; tangency does not count as an intersection here.
At first glance, it is hard to know where to begin. With enough points, one can imagine an arrangement in which, after we place several disks and cover several points, every remaining point sits squarely in a gap between the disks. Covering one of those points would then force a new disk to overlap an existing one. Any proof that places the disks one at a time would have to show that this situation can always be resolved, which is clearly difficult.
Now let us see what the probabilistic method can do. Suppose we place disks only in a fixed, regular pattern. This limits our choices but makes the arrangement much easier to analyze. The most obvious pattern puts a unit disk at every even lattice point, meaning every point with coordinates for . The plane then looks like this:

This cannot be our final strategy. Used as is, the pattern will never cover the star-shaped gaps between the disks. Instead, translate all the disks together by a random vector : add to the horizontal coordinate and to the vertical coordinate of every center. The vector is random, but all the disks move by the same rather than independently.
Because the arrangement is regular and periodic, a horizontal translation by is no different from one by , and the same is true vertically. We can therefore choose uniformly at random from the square .
Positions are relative, so randomly translating every disk is equivalent to translating the points we want to cover by . A point is covered if its translated position falls inside a disk and uncovered otherwise. Because is uniform on a square, the translated point is also uniform on some square. Its probability of being covered is the fraction of that square occupied by disks. For either square shown below, this probability is the blue area divided by the square’s total area, .

No matter where the square lies, its total area of intersection with the disks is the same. The disk pattern, as noted above, has period in both directions. Imagine sliding the square across the plane: whatever leaves through one side reenters in identical form through the other, so the total intersecting area cannot change. We need only calculate the tidiest case, shown on the left. Four quarter-circles give a total area of , or a fraction of the square.
In short, when we translate all the disks together by a random vector , every point in the plane has probability of being covered by a disk.
This observation already lets us prove a weaker result by the probabilistic method: any given set of points in the plane can be covered by pairwise disjoint unit disks. Under the random translation above, each point is covered with probability , so the expected number of covered points is
You may wonder why multiplying by the probability gives the expectation. Let us unpack the calculation for anyone who needs it; readers already familiar with the technique can skip ahead. The tool is an “indicator random variable.” Let record whether the first point is covered after the random translation: if it is covered and otherwise. The variable indicates whether the event occurred, hence the name. Define in the same way for the other three points. The total number of covered points is the sum of these four variables and is itself a random variable:
The expected number of covered points is therefore . By linearity of expectation, we can move the sum outside:
From the definition, . Therefore,
That is the full calculation. The variables are certainly not independent, but linearity of expectation lets us add their expectations without requiring independence. We will use the same technique again later. For now, the expected number of covered points is .
Some translation must therefore cover more than points; otherwise, the expectation could not exceed . Because the number of covered points is an integer, “more than ” means all points. This proves the weaker statement.
The original problem, of course, asks about points rather than . What can we do? Notice that the argument uses only the periodicity of the disk arrangement. If we keep that periodicity while packing the disks more densely, thereby increasing the probability , the same method will give a stronger result. Consider the denser honeycomb pattern below. It remains periodic in two directions, one horizontal and the other at an angle of degrees to the horizontal.

The pattern is still periodic, so the parallelogram’s area of intersection with the disks remains constant as we slide it. As the figure shows, that area is again , the area of one complete circle, because the pieces inside the parallelogram can be reassembled into a circle. The proportion has changed, however: the parallelogram has area only , so the disks occupy a fraction .
Once again, translate all the disks by a random vector , now chosen uniformly from the parallelogram shown above. A single point is covered with probability , so among 10 points the expected number covered is
As before, some translation must cover more than points, which means all points. The result follows.
The new arrangement proves the claim for points. Could an even denser one prove a stronger result? No: the honeycomb pattern already achieves the greatest possible density for a packing of disjoint unit disks in the plane. No denser arrangement exists; this is Thue’s theorem.
A stronger result is still possible. Greg Aloupis and his coauthors proved that the statement remains true for points, but their result cannot be obtained simply by changing the arrangement and repeating the argument above.
The exact number of points needed to guarantee that some set cannot be covered remains unknown. A counterexample with points is known, but the territory between and is still waiting to be explored.
Random Selection and Independent Sets in Graphs
Our third example comes from graph theory, and only the basics are needed. A graph consists of vertices and the edges that join them. Denote the vertex set by , the edge set by , and the graph by .
A set of vertices is called an independent set if no two vertices in are joined by an edge. Its size is .
The figure below gives an example. The points are vertices and the lines between them are edges. The gray vertices form an independent set, though certainly not the only one.

Finding a graph’s maximum independent set is a classic problem in graph theory. Let . Can we give a lower bound for the maximum independent-set size in terms of ? In other words, if a graph has vertices and edges, how large must its maximum independent set be?
This looks much harder than the preceding problem. A graph may have any structure, and the “worst” structures get in the way of a lower-bound estimate. But what do those worst cases look like? Following that question seems likely to plunge us into the depths of graph theory. Let us take a different route and see how neatly the probabilistic method produces an estimate.
Include each vertex in a set , independently, with probability . Let be the number of selected vertices, and let be the number of edges between them. Both and are random variables.
When , is independent; otherwise, it is not. We need an independent set before the probabilistic argument can tell us that “an independent set of size exists.” So what now? We use the alteration method, also described here as the “deletion-and-modification method”: if a random construction does not directly produce the object we want, alter it until it does. If is not independent, simply make it independent.
For each of the edges inside , choose one endpoint. Delete the chosen vertices from and call the result . Because the same vertex may be chosen more than once, we delete at most vertices. The set must be independent, and its size is at least . If , nothing goes wrong; this remains a valid, though trivial, lower bound.
As before, take an expectation and calculate . We immediately have , but what about ? Use the indicator-variable technique from the previous example. Define to equal when edge is selected and otherwise. Linearity of expectation then gives
The value is simply the probability that edge is selected. This happens exactly when both of its endpoints are selected. Because the vertices are chosen independently, the probability is . Thus and , so
This proves that there is an independent set of size at least ; in other words, . We are free to choose , so we can take the best value for the given . When , the expression is a quadratic function of whose maximum occurs at . Accounting for the probabilistic constraint and the boundary case gives the piecewise result
That was not too complicated, was it? But is the bound any good?
The probabilistic method often produces startling results, but it is no universal cure, and it does not automatically give a good answer. The quality of the result depends on the problem itself and on how the method is used. Our estimate is not bad, but it is not especially good either. The construction is still too crude.
Try a different random construction. Order all the vertices at random, and add a vertex to if it appears before all its neighbors. The rule is simple and elegant, and the resulting is already independent. Of the two endpoints of any edge, only the earlier one can possibly enter , so no two vertices in are joined by an edge.
As before, define an indicator random variable for each vertex , recording whether it enters . Then . A vertex’s inclusion depends on its neighbors. Let be the number of vertices adjacent to . The vertex and its neighbors are all equally likely to appear first, so is selected precisely when it comes first among these vertices, an event with probability . Therefore,
Because the expectation equals this quantity, at least one independent set must be this large. Hence,
This result is never weaker than the previous one and is much stronger in many cases. The proof needs only a case analysis and the Cauchy–Schwarz inequality. We have not assumed that readers know the inequality, however, and the proof would take us away from our subject, so we will omit it. The new and better result is important enough to have a name: the Caro–Wei bound on the size of a maximum independent set.
We will not analyze the bound in depth. Readers who know or enjoy graph theory can look for the deeper reason the two methods differ: identify the cases in which the first estimate loses sharpness, then see how the second construction avoids those losses. Our point here is simpler. “The probabilistic method” may give you a result, but it does not guarantee a good one. The better the probabilistic structure fits the problem, the better the result is likely to be.
Random Sampling and the Approximate Carathéodory Theorem
Graph theory offers many more examples, including Ramsey numbers, probably the one mentioned most often, and other problems in graph coloring. Those examples tend to be less concise, so we will leave graph theory after this one and visit some other fields.
Our next example comes from Roman Vershynin’s textbook High-Dimensional Probability.
We first need the ideas of a convex combination and a convex hull. A convex combination of points is a linear combination with nonnegative coefficients that sum to . Thus, if and , then is a convex combination of the . If the definition is unfamiliar, picture the plane : the convex combinations of two points are exactly the points on the line segment between them.
More generally, the convex hull of a set consists of every convex combination of finitely many elements of .
In fact, the classical Carathéodory theorem lets us replace “finitely many” with “at most .”
(Carathéodory theorem). Let . Every point can be expressed as a convex combination of at most points in .
The proof is not difficult, but it is not much fun either. We will neither prove nor use it here; interested readers can look it up. I mention it because of a natural extension. If we must use fewer points in the convex combination, we may no longer be able to reach every point in the convex hull. How closely can we approximate them instead? Another theorem answers that question.
(Approximate Carathéodory theorem). Let , and suppose every pair of points in is at distance at most . For every and every positive integer , there are points , with repetition allowed, such that
In other words, we can always find points in whose average approximates , and the approximation is quite good: the error in Euclidean distance is only . The result is surprisingly strong. We place no restrictions on the shape of , which may be very strange, yet obtain a stable rate of approximation independent of . Better still, we use only an average, the most special kind of convex combination. Let us see the proof.
Choose any point in as the new origin. The entire set then lies inside the unit ball centered at that origin, so every element has norm at most .
Take and suppose it is a convex combination of elements , with coefficients . We will approximate using of these elements, chosen randomly rather than deterministically. Let for be independent, identically distributed random variables, each taking the value with probability . By definition,
In the spirit of the law of large numbers, we use to approximate . We next calculate the approximation error we want to control, or rather its square, which is easier to handle:
The second equality comes from expanding the square. The variables are independent and have expectation , so the expected cross terms vanish, just as they did in our first example. It remains to calculate . The index does not matter because all the have the same distribution. A simple estimate gives the upper bound:
Here we have used the fact that every element has norm at most . It follows that
There must therefore be some realization of the variables for which
Taking square roots gives exactly the desired result.
This, too, is a classic proof. The technique is known as Maurey’s empirical method, though in spirit I see no essential difference between it and Erdős’s probabilistic method.
Random Matrices and Linear Codes
Our final example comes from coding theory. It runs a little long, not because it is difficult, but because we first need several basic definitions.
A set of length- binary strings is called a length- binary code. Its elements are called codewords.
The Hamming distance between two -bit binary strings is the number of positions in which they differ; denote it by . For example, and have Hamming distance because only the first and last bits differ.
For a binary code , define its minimum Hamming distance to be the smallest Hamming distance between any two distinct codewords:
d(C)=\min_{\substack{x,y\in C\\x\neq y}}d_H(x,y).From now on, we will call simply the Hamming distance of and omit the word “minimum.”
A larger Hamming distance means greater separation between codewords, which makes transmission errors easier to correct.
For fixed , however, the achievable Hamming distance generally decreases as the code’s size grows. In a larger code, it is harder to keep the codewords far apart; they become “crowded together.” At the extreme, if contains every binary string, its Hamming distance is .
We want a binary code to be as large as possible while maintaining a given Hamming distance . A larger code means a higher code rate and less redundancy. The question is:
Given a codeword length and a desired distance , if a binary code must satisfy , what lower bound can we guarantee for ?
The exact answer is not easy to find. We seek only a reasonably good lower bound, a statement that “a at least this large can always be found.” We do not need the probabilistic method yet. First, consider an elegant volume argument.
Start with an empty set and add codewords one by one. Each new codeword must differ from every existing codeword in at least positions, meaning it must be at Hamming distance at least from each one. Continue until no more codewords can be added. The result is a binary code .
At that point, every binary string outside the code must differ from some codeword in at most positions; that is, . If differed from every codeword in at least positions, we could still add it to , contradicting the fact that the construction had stopped.
Let be the set of all strings at Hamming distance at most from . The preceding paragraph says that every belongs to some with . Equivalently, the sets cover all of :
The size of does not depend on ; denote it by . The union on the left has at most elements, so the covering requires
The code produced by this construction therefore satisfies
This gives a concise lower bound for our question: the largest has size at least . In the Hamming metric, is a “ball” centered at with radius . We have just calculated the minimum total volume needed for a collection of such balls to fill the entire space. This classical method is therefore called a “volume argument,” and similar arguments appear in many other problems.
We can, of course, calculate the volume . The members of are the binary strings containing at most ones, so its size is the sum of binomial coefficients . You can substitute this into the expression above if you wish. In communications, an entropy inequality is often used to estimate the result further. We do not need that step here, so we will leave the bound in its present form.
Now, at last, we reach the probabilistic part of the example. We want our binary code not only to be as large as possible and have as great a Hamming distance as possible, but also to have a particular structure: every codeword should be generated by a single matrix. Such a code is called a linear code. Here is the definition.
From this point on, treat not just as symbols but as numbers that can be added and subtracted, with arithmetic performed modulo :
Take a binary matrix . It encodes a length- binary string as . Every operation in the matrix multiplication is performed modulo , so the result is still a binary string, now of length .
The set of all possible encoded results,
is a linear code.
A linear code has algebraic structure that a general binary code lacks, and encoding reduces to a matrix multiplication. Linear codes are fundamental objects in coding theory and communications, so let us add linearity to our earlier question:
Given a codeword length and a desired distance , if a linear code must satisfy , what lower bound can we guarantee for ?
The previous volume argument no longer works easily because it gives us no simple way to guarantee that the resulting is linear. A volume proof is not impossible, but it is difficult, or at least too difficult for light reading here. So we will bring in the probabilistic method. First, however, we need a property of linear codes that simplifies the Hamming-distance calculation.
Under arithmetic modulo , the Hamming distance between is exactly the number of ones in . Computer-science students will recognize this addition as bitwise XOR: equal bits produce and different bits produce , so the number of ones is precisely the number of positions where the strings differ. We give “the number of ones in a binary string ” a name: the Hamming weight of , denoted by .
Because matrix generates a linear code, the sum of two codewords is , which is itself a codeword. We can therefore rewrite the Hamming distance of as
Indeed, the Hamming distance between distinct is the Hamming weight of . Conversely, for any , its Hamming weight is the Hamming distance between and . The two definitions are therefore equivalent. To make the Hamming distance at least , we need only ensure that every nonzero codeword has Hamming weight at least .
With this important property in hand, we can finally use the probabilistic method.
Choose at random, with every entry an independent uniform random bit. For any fixed nonzero , the product is a uniformly random binary string of length whose bits are independent and uniform. Every bit of is equally likely to be or , and different bits depend on different columns of , so they are independent.
What is the probability of the bad event that “a random binary string has Hamming weight less than ,” meaning that it contains fewer than ones? As before, it is the appropriate sum of binomial coefficients divided by the total number of strings:
For convenience, continue to call the numerator , although we will not use its geometric interpretation as the “volume of a ball” here.
Across all nonzero input strings, we can estimate the probability that at least one encoded codeword has Hamming weight less than by
The first inequality is the union bound from probability, .
As long as this probability is less than , the “bad event is not inevitable.” There must then be a fixed for which every nonzero input string satisfies
The following condition is sufficient to make the probability less than :
In other words, whenever and satisfy this inequality, there is a matrix that produces a linear code with Hamming distance at least ; call that code .
How large is this linear code ? Its size is , because must map distinct input strings to distinct results . If , then addition modulo would give , and hence . But , contradicting the requirement that every nonzero input produce a codeword of Hamming weight at least . Thus . There are input strings, and multiplying them by produces distinct results, so .
Even after strengthening the requirement from general binary codes to linear codes, we have obtained almost the same result as the volume argument. The only possible differences come from rounding and constants, because a linear code’s size must be a power of . This is deeply satisfying: we strengthened the conditions at almost no extra cost.
You may suspect that this nearly cost-free strengthening is possible only because both bounds are loose. The answer is that we do not know. The result can be improved, but we still do not know how good optimal general binary codes and optimal linear codes can be. Nor do we know whether the same nearly lossless strengthening is possible for optimal codes. Even so, the lower bound proved here is a classic and important benchmark in coding theory, usually grouped under the Gilbert–Varshamov bound.
Conclusion
Five examples are enough for an article already this long, so let us stop here. Although they come from different fields, the examples share one feature: each leaves some margin for error, whether in an estimate or an inequality. That margin is difficult to exploit in a deterministic proof. The probabilistic proofs above use it precisely without wading deep into complicated structures. They touch the obstacles lightly, clear them, and reach the result. These are proofs as art.
Beyond the art, there is technique. To be honest, extracting reusable proof techniques from these few arguments may be difficult. We see ingenious proofs in their finished form, not the process by which anyone first discovered them. Some may be products of repeated refinement in modern teaching and may never have been easy to find. That is all right. If we see enough of them, perhaps one day we will find a use for them ourselves. Mathematics need not be studied too instrumentally. May each of us continue to feel its beauty. Let us end with this line:
Without doing a few seemingly useless things, how could one pass this finite life? —[Qing] Xiang Hongzuo
 爱发电(点击图片跳转)