A Lower Bound for Randomized Sorting: An Introduction to Yao's Principle
A deterministic comparison-based sorting algorithm requires comparisons on its worst-case input. But how many comparisons does a randomized algorithm make in expectation on its worst-case input? This article introduces Yao’s principle and uses it to derive a lower bound for randomized sorting.
Author: silverxz
Reviewed by: phy东西
Introduction
The lower bound on the worst-case number of comparisons made by a deterministic comparison-based sorting algorithm is a classic result. It appears in textbooks such as Introduction to Algorithms and in most algorithms courses, so many readers will already know it. (This article assumes only an introductory knowledge of algorithms and probability theory. Following the usual convention in algorithms, lg uses base .)
But how many comparisons does a randomized algorithm make in expectation on its worst-case input?
If you have never encountered randomized algorithms, you may suspect that allowing randomness cannot magically make an algorithm better. Yet some randomized algorithms really do seem magical.
Quicksort is one example. If it chooses pivots by a fixed rule, ordinary quicksort can take time on its worst-case input. Choosing pivots at random, however, keeps its expected complexity at even on the worst input. That may not seem magical enough, since plenty of other sorting algorithms run in . A more striking example is Freivalds’ algorithm. It has nothing to do with sorting, but it is so concise and ingenious that it deserves a brief introduction. The algorithm solves the following problem.
Problem: Given three matrices , determine whether equals . In other words, verify whether a matrix multiplication result is correct.
The most direct approach is, of course, to multiply and , then check whether equals . Its computational cost is that of matrix multiplication, or by the naive method. It is hard to imagine doing better than matrix multiplication itself, yet Freivalds found a randomized method that astonishes almost everyone who encounters it for the first time.
Lemma (Freivalds’ algorithm)
Let be a random vector of length with entries. Then:
- if , then always holds;
- if , then .
To keep the main text shorter, the proof appears in Note 1. It is quite simple, too.
Using this lemma, choose independent random vectors . Since multiplying a matrix by a vector takes quadratic time, at a total cost of we can compute and compare each with , for . If any pair differs, then . If every pair is equal, the algorithm simply declares that . By the lemma, the probability of a false result—the actual case is , but every and the algorithm is fooled—is at most . When is fixed as a constant, this is an algorithm.
The fastest matrix-multiplication algorithms known today are still a long way from , yet Freivalds’ remarkably simple method sidesteps matrix multiplication altogether. The price is a small probability of error, but that is easy to manage: repeat the test a few more times. The error probability falls exponentially and soon becomes smaller than the chance of hardware failure, system failure, or the server room exploding (Note 2).
Does this example make randomized algorithms seem more powerful? Many of them solve, with remarkable simplicity, tasks that are much less straightforward for deterministic algorithms. Similar ideas underlie various hashing algorithms and their extensions, including the Bloom filter, which you may have heard of. In essence, they construct a random “fingerprint” as cheaply as possible, then use it to identify or compare objects as reliably as possible.
This does not mean that randomized algorithms truly have better asymptotic complexity than deterministic ones. In the case of Freivalds’ algorithm, we do not know whether an deterministic matrix-multiplication algorithm exists. In theory, one might. It would give us an deterministic test for whether equals , putting the randomized and deterministic algorithms on equal footing. Even if such an algorithm exists, however, it would surely be extremely complicated. The randomized algorithm we just saw is remarkably simple, and that is what makes randomized algorithms so impressive.
Now return to sorting. Could a randomized algorithm somehow beat the deterministic lower bound, using fewer than comparisons in expectation on its worst-case input? There is no need to keep you in suspense: the answer is still no. To prove it, we need a tool for establishing lower bounds on randomized algorithms, one that shows even randomization cannot work unlimited miracles.
Yao’s Principle
The tool we will introduce is Yao’s minimax principle, usually shortened to Yao’s principle. It comes from Andrew Yao’s 1977 work and is one of the oldest and most fundamental tools for lower-bound analysis of randomized algorithms. Its central idea is to view the relationship between an algorithm and its input as a game.
You may not know what a “game” means in this context, so consider a familiar example: rock–paper–scissors. Let be sets and a binary function on them, defined as follows:
The game of rock–paper–scissors has two players, whom we will call Alice and Bob. They choose an element from and , respectively, and those choices determine the outcome. In game-theoretic language, the elements of are Alice’s strategies (Note 3), while the elements of are Bob’s strategies. Once they have chosen, the function gives the payoff or cost associated with that pair of strategies.
What does this have to do with algorithms? For the sorting problem, let be the set of all deterministic comparison-based sorting algorithms, the set of all inputs of size , and the number of comparisons algorithm needs to sort input . Alice and Bob are still playing a game. Think of Alice as the algorithm designer and Bob as an adversary: Alice wants to choose the best possible algorithm and make as small as possible, while Bob wants to choose the worst possible input and make as large as possible.
A worst-case analysis of a particular algorithm —for example, the number of comparisons that a sorting algorithm makes in the worst case—allows Bob to attack with the worst input . The maximum number of comparisons can be written as
From this game-theoretic perspective, the familiar lower bound says that no matter which algorithm Alice chooses, Bob can use his knowledge of to find a sufficiently bad input on which algorithm requires comparisons. Notice the order of play: Alice chooses the algorithm first, and Bob, knowing her choice, can tailor his attack. In symbols, there is a constant such that, for all sufficiently large ,
The left-hand side is the number of comparisons required by the best algorithm on its worst input of size . Observe how the expression captures the order just described. If we add parentheses, it becomes
The inner operates on the value selected by the outer operation and, for this , chooses the input that maximizes . In other words, Bob knows before maximizing , which captures the order of play. This point matters because we will repeatedly encounter interleaved and operations.
So far, we have only restated the familiar result for deterministic algorithms in different language. With a little time, it should be straightforward to follow.
We have viewed the relationship between deterministic algorithms and inputs as a game. The crucial next question is: what about randomized algorithms?
First consider what a randomized algorithm is. Unlike a deterministic algorithm, it can generate random numbers and make decisions according to their values.
If we fix every random number it generates, a randomized algorithm becomes deterministic. For example, if a C program obtains random numbers with rand, fixing the seed passed to srand fixes the sequence produced by rand. We can therefore regard a randomized algorithm as a random variable whose possible values are deterministic algorithms.
If that last sentence sounded obscure, remember that a random variable need not take numerical values. Drawing one card uniformly at random from a deck defines a random variable whose possible values are the cards and whose distribution is uniform. Similarly, a randomized algorithm selects one algorithm from a set of deterministic algorithms, so it is a random variable taking values in that set. Put more plainly, a randomized algorithm randomly chooses one algorithm from a collection of deterministic algorithms. We will need this probabilistic formulation below, so it is worth taking a moment to understand it.
In mathematical language, let denote the set of all probability distributions over . An element is therefore a probability distribution, and a randomized algorithm is a random variable following some distribution , written (Note 4).
Return to the contest between Alice and Bob. We now allow Alice to choose a randomized algorithm. She no longer has to commit to a single fixed algorithm and let Bob exploit the weaknesses of . Instead, she can choose a random variable over , denoted by . This randomized algorithm makes Bob’s attack more difficult.
That description alone may not make the benefit obvious, so return to rock–paper–scissors. If Alice can use only a deterministic strategy, Bob always wins. The order of play means that Bob effectively watches Alice make her move before choosing his own. If Alice can instead use a randomized strategy, choosing rock, paper, or scissors with probability each, Bob can no longer target her choice.
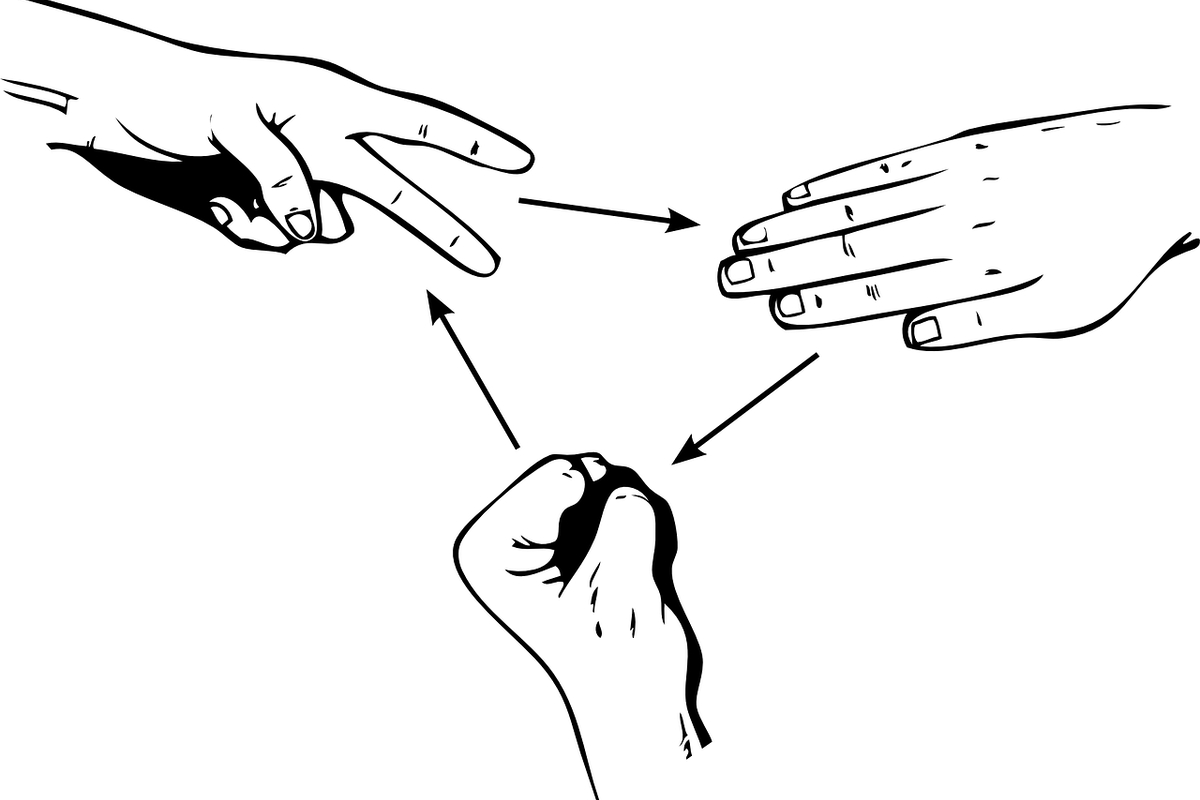
This example shows why a randomized algorithm can have an advantage. The order of play has not changed: Bob can still know Alice’s strategy in advance. But because the strategy itself is random, knowing that “Alice chooses uniformly among rock, paper, and scissors” gives him no way to counter it.
We already know that the worst-case number of comparisons made by the best deterministic sorting algorithm can be expressed as
What, then, is the expected number of comparisons made by the best randomized algorithm on its worst-case input? Since Alice can choose an algorithm at random, the variable beneath is no longer but
Alice specifies a randomized strategy with distribution . Bob then chooses an input to attack that strategy, and we calculate its expected cost .
This expression is plainly difficult to evaluate. We do not even know all the deterministic algorithms, much less every distribution over them. Yao’s principle, however, can transfer the randomness from Alice’s side to Bob’s. That makes the problem much simpler, because we know exactly what contains: all permutations of through . We can now state the theorem.
Theorem (Yao’s minimax principle)
Let be two finite sets and let . For every random variable over , denoted by , and every random variable over , denoted by ,
Proof
The proof is short, so we will complete it before explaining what the theorem means.
The first and last lines use the elementary inequality
The maximum is at least the average, which is at least the minimum. Straightforward, isn’t it? Such a basic inequality rarely yields anything useful by itself. The crucial step here is exchanging the order of expectation in the second line. The theorem assumes that are finite, so these expectations are finite double sums whose order can be exchanged. That completes the proof.
In fact, the proposition does not require both sets to be finite. Finiteness was used only to exchange the expectations in the second step, and it is enough for one of the two sets to be finite, because a finite sum and an integral can be interchanged. The lower-bound proof for sorting later in this article actually uses this version, in which one set is infinite and the other finite. Writing it as a separate theorem would be cumbersome, so we will not do so (Note 5).
If both sets are infinite, conditions such as allow the integrals to be exchanged using Tonelli’s theorem. Yao’s principle can therefore be extended, but we will not need that version. Readers without a mathematical background can safely ignore it.
The proof is remarkably simple, but the important question is not how the theorem is proved; it is what the theorem tells us. In the statement, are abstract sets with no assigned meaning, and is an abstract function. Give them their usual interpretation, and we are back to the game between algorithm designer Alice and adversary Bob. The set contains every deterministic algorithm Alice may choose, every concrete input Bob may choose, and is the cost incurred by algorithm on input , such as its running time or number of comparisons. Alice wants the algorithm that makes as small as possible; Bob wants the input that makes as large as possible.
As discussed above, the random variable over denoted by represents one of Alice’s randomized algorithms. The left-hand side, , is Bob’s strongest attack on the randomized algorithm : he chooses the input with expected cost as large as possible, denoted by . By contrast, the random variable over denoted by represents a randomized input strategy for Bob. Alice chooses the deterministic algorithm with the smallest expected cost against that distribution. The expected cost of this algorithm is the right-hand side, .
Once we understand the two sides, the inequality itself becomes clear. To lower-bound the expected cost of a randomized algorithm on its worst input—the left-hand side—we may instead analyze the expected cost of the best deterministic algorithm against a random input —the right-hand side. The latter is a lower bound for the former. More concretely, suppose we want to prove . The inequality tells us that it is enough to prove , after which
Readers who have followed this far may wonder whether this method analyzes only one randomized algorithm . Our original goal was a lower bound for every randomized sorting algorithm, not merely one particular algorithm. Those sound very different. But the theorem allows arbitrary and , so we immediately obtain the following corollary.
Corollary
Let be two finite sets and let . Then
In particular, for any random input—that is, any random variable over , denoted by —
Proof
As noted above, in the theorem are arbitrary. Thus,
Since this inequality holds for every , it still holds for the that minimizes its left-hand side. Therefore,
Repeating the same argument for gives
We have immediately turned a statement about one randomized algorithm into a statement about all randomized algorithms. The result gives us a standard pattern for lower-bound analysis. To prove that every randomized algorithm has high cost—that exceeds some value—it is enough to show that, for some random input , every deterministic algorithm has high cost—that exceeds that value. This is what we mean by transferring randomness from the algorithm to the input.
Some readers may ask: this is only an inequality, and its proof is extremely simple. Is the resulting lower bound genuinely useful, or could it be very loose and utterly trivial?
If that question occurred to you, it is an excellent one. The answer reveals the power of the result. When are finite, we can in fact prove
The is attained, so equality holds. If you can construct the random variable , or equivalently the distribution , that attains the maximum on the right, the resulting lower bound is tight: transferring the randomness loses nothing. In practice, finding a sufficiently difficult is often the hard part of applying Yao’s principle. The harder the distribution you construct, the tighter the lower bound you obtain. Yao’s principle is not a theorem that can be applied mechanically; it often appears only as the final step of a larger proof.
This equality follows directly from the von Neumann minimax theorem in game theory. Its proof is unrelated to our subject, so we will omit it. The equality need not hold in the infinite case. This also explains the name “Yao’s minimax principle.”
A Lower Bound on Comparisons in Randomized Comparison-Based Sorting
We can now answer the question posed at the beginning. First, let us review the basic deterministic result, because we will use the same decision-tree model. The review will be brief; it is only meant as a refresher.
Theorem
The number of comparisons made by a deterministic comparison-based sorting algorithm has a lower bound of .
Proof
“Comparison-based” means that the algorithm cannot directly use the specific values of the elements. It can learn their ordering only by asking questions of the form . In sorting problems, we ordinarily assume that no two elements are equal.
Consider a deterministic sorting algorithm. Since the algorithm is deterministic, its comparison strategy is completely fixed: which two elements it compares next depends entirely on the outcomes of all earlier comparisons.
We can therefore unfold the algorithm’s entire execution into a binary tree called a decision tree. Each node represents the comparison the algorithm makes when it reaches that point. For example, the root might be , meaning that the algorithm begins by comparing . If the root’s left child is , then after finding , the algorithm next compares . If the root’s right child is , then after finding , it next compares . Because the algorithm is deterministic, its behavior uniquely determines the whole tree.
The algorithm follows the left or right child after each comparison and continues downward. When it stops, it makes no further comparisons and has reached a leaf of the decision tree, where it outputs one fixed ordering. Thus, every leaf corresponds to one permutation. If the algorithm is correct, inputs with different orders cannot reach the same leaf; otherwise, at least one of them would receive the wrong output. There are possible orders, so the decision tree has at least leaves.
Let the decision tree have height . A binary tree of height has at most leaves, so
By Stirling’s formula,
The algorithm therefore needs at least comparisons to sort the input corresponding to a deepest leaf.
That completes the review. We now want to analyze randomized algorithms, for which the decision-tree model no longer seems applicable. One important reason the model works for deterministic algorithms is that their comparison strategy is fixed. Whenever all previous comparison outcomes are the same, the next pair of elements to compare is fully determined, allowing the execution to be expanded into a binary decision tree. A randomized algorithm breaks this property: its next comparison may itself be chosen at random.
This is precisely where Yao’s principle helps. It shifts the randomness from the algorithm to the input, making the algorithm deterministic again and restoring the decision-tree model. We have laid enough groundwork, so let us proceed directly to the proof.
Theorem
The expected number of comparisons made by a randomized comparison-based sorting algorithm on its worst-case input has a lower bound of .
Proof
Recall Yao’s principle: we need a distribution over random inputs that makes the problem difficult for every deterministic algorithm. We noted that constructing is often the hard part. Here, however, there is a natural choice that readers have probably already guessed: the uniform distribution. In sorting, all elements and all permutations have equal standing. There is no reason to favor one over another, so trying the uniform distribution is the most natural approach.
Let { all deterministic comparison-based sorting algorithms }, { all permutations of 1 through n }, and let the number of comparisons algorithm a makes to sort input x. Let be the uniform distribution over . To apply Yao’s principle, we must lower-bound , the expected number of comparisons made by a deterministic algorithm under the uniform distribution. This is precisely what decision trees allow us to analyze.
For a deterministic algorithm , consider its decision tree again. The distinct inputs reach distinct leaves. Let the depths of these leaves be . The expected number of comparisons made by on this random input is the average of all these depths:
Estimating the right-hand side requires only a little mathematics. First, we have the Kraft inequality
Do not be alarmed; its intuitive proof is simple. First imagine a full binary tree, in which every node has either two children or none. Assign every leaf at depth the value . Then repeatedly merge pairs of sibling leaves, as in the game Merge Watermelon: remove two sibling leaves, each worth , and assign their parent, now a new leaf, the value . Keep merging until only the root, with value , remains. Thus, for a full binary tree, the leaf depths satisfy . In a binary tree that is not necessarily full, some nodes have only one child. Contract each such edge by merging the node with its only child, making the tree full. That edge only increased the leaf depths, so the original sum on the left can only be smaller. Hence .
One final bit of mathematics remains. Jensen’s inequality says that if, on , the function is convex, positive real numbers satisfy , and , then
We know that is convex. Therefore,
Here plays the role of in the inequality, and plays the role of . Since the result holds for every algorithm ,
Yao’s principle now gives
In other words, every randomized algorithm has some sufficiently bad input on which its expected number of comparisons is also of order .
Randomized Sorting Algorithms That May Err
At this point, the problem seems fully resolved, though the answer is a little disappointing: there is no miracle, and randomized algorithms cannot break the barrier.
Careful readers may still have a question. Freivalds’ algorithm, our opening example, allows a small probability of error, and that is a major reason for its excellent performance. Although our proof seemed to cover every randomized algorithm, it did not: it covered only algorithms that never err. The randomized algorithm is a random variable over , and consists entirely of correct deterministic algorithms. No matter how they are randomized, therefore never errs either. Could a randomized algorithm become miraculously better if we allowed some probability of error? As an encore, this section answers that question as well. It is slightly more complicated than what came before, but not substantially more difficult.
The preceding analysis missed randomized algorithms that may err because did not contain incorrect deterministic algorithms. Our first step should therefore be to enlarge so that it includes them.
The problem is that a deterministic algorithm in this larger set may be spectacularly wrong. Consider a simple and rather foolish randomized algorithm: with probability , it returns the input unchanged; with probability , it runs a correct deterministic sorting algorithm such as merge sort. This is certainly a randomized sorting algorithm that may err, with an error probability of at most . To include it, must contain the “return the input unchanged” algorithm, which is wrong almost all the time. Yet that algorithm makes no comparisons at all. If it belongs to , then
which tells us nothing.
The underlying problem is that we want to control the randomized algorithm’s error probability, and the comparison bound should depend on that probability. Yet a randomized algorithm with bounded error may still be a distribution over deterministic algorithms that are wildly inaccurate, while our cost function records only the number of comparisons and says nothing about error.
The framework of Yao’s principle allows only one function , so we seemingly cannot use separate functions for comparison cost and error. What can we do? Readers familiar with optimization may recognize a standard device: Lagrangian relaxation. This technique lets us combine two quantities that we want to optimize subject to a joint constraint.
Let be the set of all deterministic algorithms, whether or not they sort correctly. Leave unchanged as the set of all inputs of size , namely the permutations. Redefine using a parameter :
Here is our original , the number of comparisons made by algorithm on input , while is defined by
Thus, the comparison count and the error indicator are combined using the coefficient in . Saying that the error probability is at most for a randomized algorithm means that it satisfies
Let us apply the same Yao’s-principle analysis to these definitions of .
Again choose the uniform distribution over , denoted by , and consider a deterministic algorithm under this random input. Suppose algorithm correctly sorts, among all inputs, a fraction ; that is, it correctly sorts of them.
The case creates a minor nuisance, so first exclude algorithms that are wrong on every input. A better option always exists: an algorithm that outputs one fixed permutation without making any comparisons is still correct for exactly one input. We may therefore discard the case and assume .
Following the earlier decision-tree argument, to sort these distinct inputs correctly, the inputs must reach different leaves. The tree therefore has at least distinct leaves. Let the depths of these distinct leaves be . The Kraft inequality still holds, so the same Jensen’s-inequality argument gives their average depth:
The details are left for the reader to verify. It follows that
Notice that this bound depends only on and ignores every other feature of the algorithm. In effect, it reduces the complexity of the algorithm set . We no longer need to consider every individually; we need only consider the fraction of inputs it sorts correctly, . Applying Yao’s principle, for every randomized algorithm we have
The left-hand side is not yet what we want, because now combines the number of comparisons with the cost of error. Let be a randomized algorithm whose error probability is at most , so that
The definition of then gives
Rearranging and substituting the inequality from Yao’s principle yields
This is the form we wanted. It says that, with error probability at most , a randomized algorithm makes at least the quantity on the right in expected comparisons on its worst-case input.
This is not yet the final result, because the expression still contains . It holds for every , so we want to choose to maximize the right-hand side and make the inequality as tight as possible. In other applications, we would normally differentiate with respect to and find the maximum. Here, the inner makes direct differentiation awkward. A geometric treatment could interpret the expression through an upper convex hull, but explaining that approach would take some work, and readers may not know what a convex hull is. We will take the bluntest route and calculate it directly.
First, takes the discrete values , which is inconvenient. For a given , we plainly have
We may therefore work with the continuous case and still obtain a lower bound. Define
We begin with the inner minimum. For fixed , define
Differentiating—and remembering that our has base —gives
The minimum is therefore attained at the critical point . Because, in , the restricts to , we need a short case analysis. When , the minimizer lies within the interval. When , for the derivative , so the minimum occurs at . Substituting into gives
This removes the outer . We want to maximize . Direct calculation verifies continuity at the breakpoint, where . Since, when , decreases monotonically, we can discard the part with while finding the maximum and consider only .
Differentiating gives
The maximum occurs at the critical point . One boundary issue remains. If , substituting it into gives , and then . If , then is less than and remains a valid, though trivial, lower bound on the number of comparisons, which is always nonnegative. We may therefore use the same bound without compromising correctness.
Returning to the result derived above, we can finally write
We have proved the following theorem.
Theorem
If a randomized comparison-based sorting algorithm has error probability at most , then for every positive integer , there is an input of size on which the expected number of comparisons made by is at least .
For a constant error probability, this quantity is still of order . Thus, even randomized sorting algorithms that may err cannot break this lower bound.
Interestingly, achieving the factor is extremely simple. Consider the foolish algorithm mentioned earlier: with probability , it produces a random, probably incorrect ordering; with probability , it runs a deterministic sorting algorithm. This produces a randomized algorithm whose expected comparison count is of order . Randomization truly offers little extra leverage in sorting. This concludes our use of Yao’s principle to analyze randomized algorithms through the example of sorting.
Conclusion
This article has introduced Yao’s principle and used it to analyze randomized sorting algorithms. Now that we have reached the end, you may feel that we used no advanced mathematics, devised no ingenious algorithm, and proved the central theorem with an argument so simple that it seemed almost trivial. Some readers may find that disappointing.
Yet many important results matter not because they are abstruse or technically intricate, but because they offer a fresh and clarifying point of view. The heart of Yao’s principle is not its two-line proof; it is the insight that an algorithmic problem can be viewed as a game. Once that insight gives us the right structure, the theorem follows naturally, and the resulting theory is concise and elegant.
As noted above, this result is due to Andrew Yao. Born in 1946, Professor Yao received the Turing Award in 2000. One reason for choosing this topic is that December 24 this year will be his eightieth birthday. We wish him good health.
Remarks
This section collects proofs omitted from the main text and additional comments on some of its content. A few notes require more mathematical background than the main article; read them as needed.
- Note 1. We prove the lemma stated in the main text.
Proof
If , then plainly . We prove that if , then .
If , then is not the all- matrix and must contain a nonzero entry. Suppose this entry lies in row , column . If vector has its th component changed from to , then the vector has its th component increased by ; conversely, changing it from to decreases that component by . Thus, when every other component of is fixed, at least one of the two possibilities for the th component, or , satisfies . Therefore,
Note 2. Randomized algorithms with bounded running time and a small probability of error are called Monte Carlo algorithms. They have no connection to Monte Carlo sampling beyond sharing a name derived from Monte Carlo and its famous casino. As discussed in the main text, repeating the algorithm reduces its error probability exponentially.
By contrast, randomized algorithms that never err but have random running times are called Las Vegas algorithms, after the gambling city of Las Vegas. A Las Vegas algorithm always returns a correct result. Its expected running time is usually required to be bounded, but its worst-case running time need not be. For certain random sequences, it may run for a very, very long time. Imagine an extremely foolish sorting algorithm that randomly shuffles the data, checks whether they are sorted, and, if not, repeats: shuffle, check, and so on until the random shuffle happens to put the data in order. This is a Las Vegas algorithm. If it halts, the data are certainly sorted; but it may also run forever and never halt.Note 3. Strictly speaking, the strategies described here are called pure strategies in game theory, meaning deterministic strategies. The randomized strategies discussed later are called mixed strategies. As explained in the main text, a mixed strategy is a random variable over pure strategies.
Note 4. A randomized algorithm can be regarded as a random variable, but strictly speaking, a random variable need not be a randomized algorithm because its distribution may not be sampleable. This raises minor computability issues. Similar issues mean that our later discussion of whether the bound from Yao’s principle is tight applies more directly to the game model and may leave a small gap between that model and an actual algorithm. This almost never causes a real problem. Readers unfamiliar with the issue can ignore it, and we will not draw a strict distinction here.
Note 5. Strictly speaking, when a set becomes infinite, a maximum or minimum need not be attained; values may only approach it arbitrarily closely. Mathematics handles this by replacing , which denote maxima and minima, with , which denote suprema and infima. Because this article assumes no mathematical background, introducing those new concepts would add unnecessary cognitive load. The distinction also makes little difference here, so the main text sacrifices a little rigor and continues to use , including in the proof of the sorting lower bound.
 爱发电(点击图片跳转)